


Recompute what your LLM traces cost, offline, from an OpenTelemetry, Langfuse or Phoenix export, with cache and reasoning tokens priced, and see where your observability tool's totals disagree.
"the Cost ($) column shows the observation-level cost of the root span, which is always $0.00 since spans cannot carry usage" — langfuse#16077, still open
The dashboards that show you LLM spend compute it once, at ingest, from a price table you don't control. Root spans show $0.00 because only the child calls carry usage (langfuse#16077); the per-user total sums only the top 20 users (#18210); the OpenAI priority tier is billed at the default rate (#13780); cache tokens get dropped on the way in (mlflow#22745) or never reported (ollama#15758); and a cost you computed yourself is re-derived and overwritten (phoenix#13655). When the invoice arrives, nothing lets you re-price the traces and find the gap.
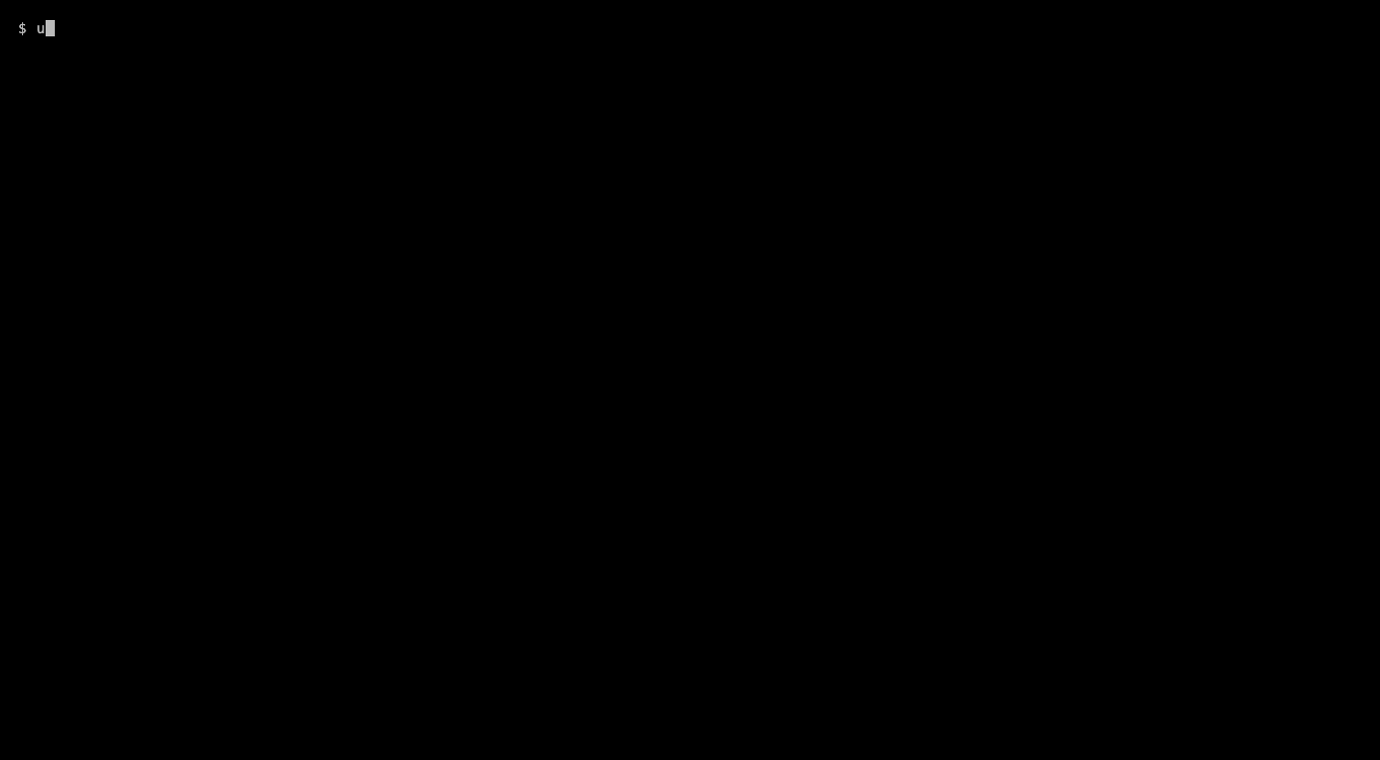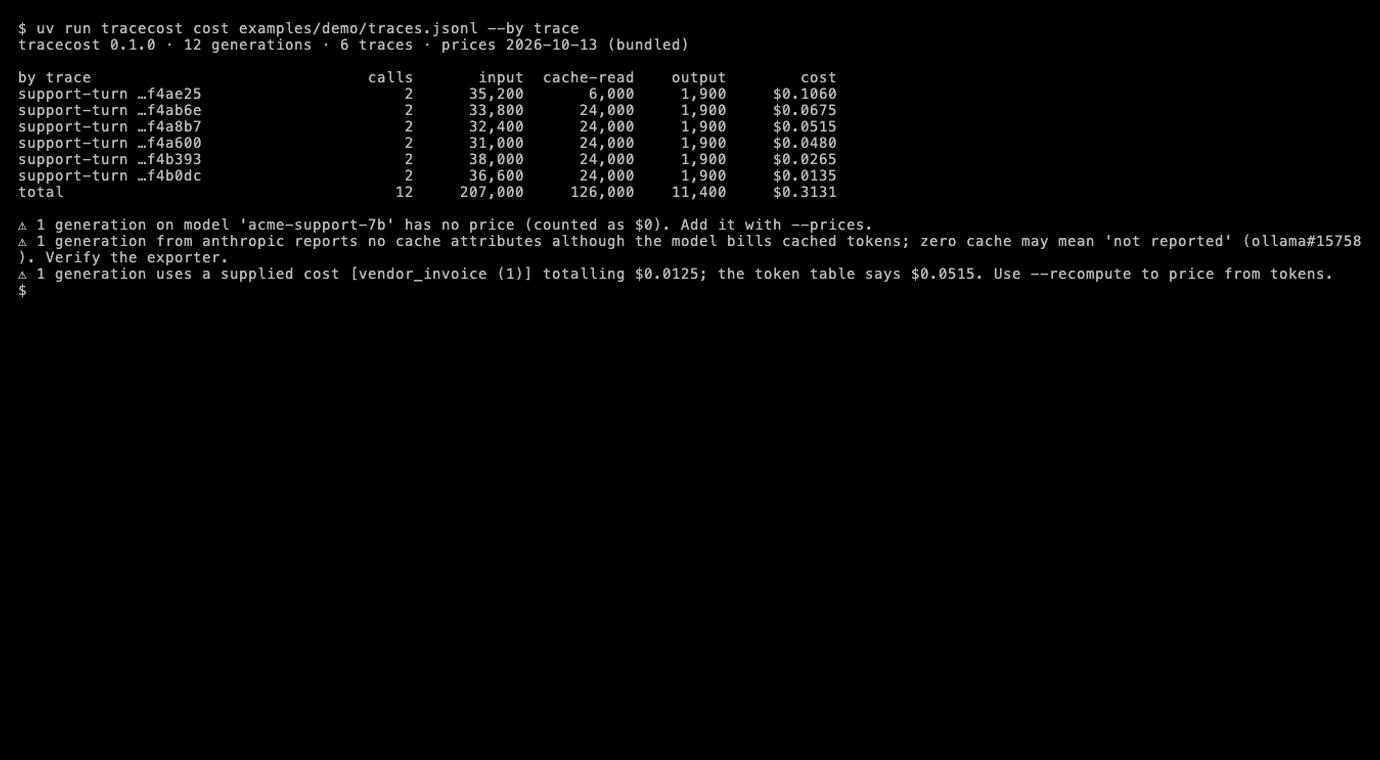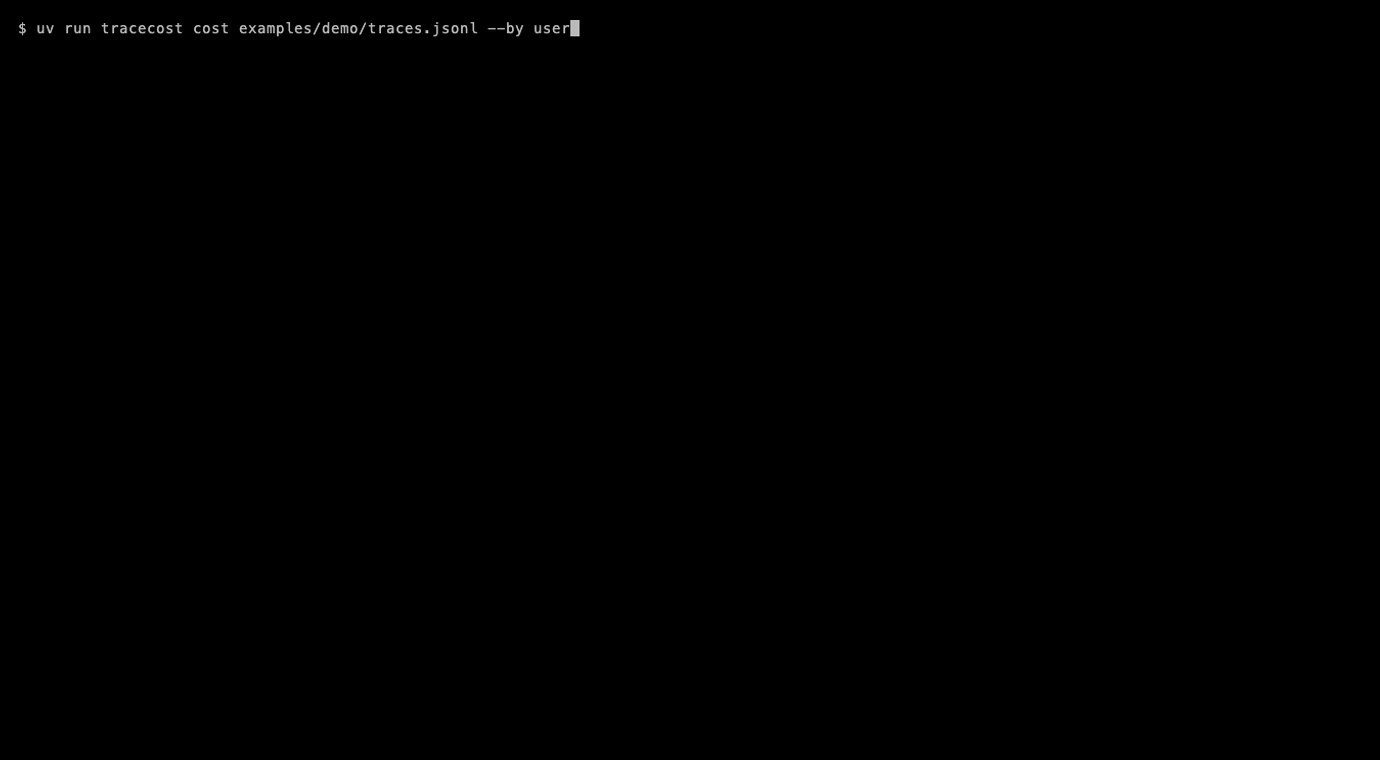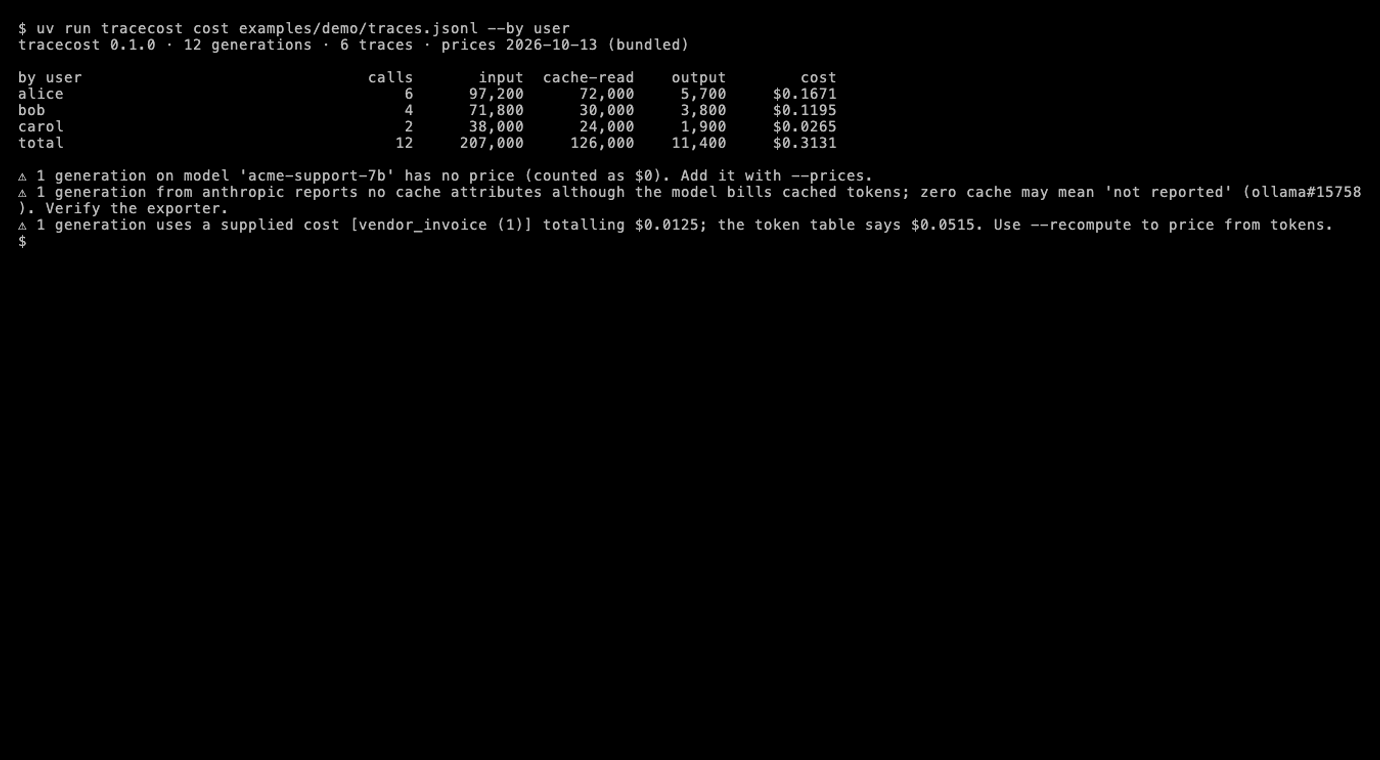
$ tracecost cost examples/demo/traces.jsonl --by trace      # in a clone of this repository
tracecost 0.1.0 · 12 generations · 6 traces · prices 2026-10-13 (bundled)

by trace                              calls       input  cache-read    output        cost
support-turn …f4ae25                      2      35,200       6,000     1,900     $0.1060
support-turn …f4ab6e                      2      33,800      24,000     1,900     $0.0675
support-turn …f4a8b7                      2      32,400      24,000     1,900     $0.0515
support-turn …f4a600                      2      31,000      24,000     1,900     $0.0480
support-turn …f4b393                      2      38,000      24,000     1,900     $0.0265
support-turn …f4b0dc                      2      36,600      24,000     1,900     $0.0135
total                                    12     207,000     126,000    11,400     $0.3131

⚠ 1 generation on model 'acme-support-7b' has no price (counted as $0). Add it with --prices.
⚠ 1 generation from anthropic reports no cache attributes although the model bills cached tokens; zero cache may mean 'not reported' (ollama#15758). Verify the exporter.
⚠ 1 generation uses a supplied cost [vendor_invoice (1)] totalling $0.0125; the token table says $0.0515. Use --recompute to price from tokens.
Six conversation turns of a support agent: each root invoke_agent span has a gpt-5 planner
call (reasoning tokens; one turn on the priority tier), a tool call, and a claude-sonnet-4-5
answer with prompt caching. The warnings are the point: one turn ran on a self-hosted model the
table doesn't know, one exporter dropped the cache attributes, and one call carries a cost from
a vendor invoice that is a quarter of what the token table says. The data is synthetic and
generated by examples/demo/make_demo.py.
uvx tracecost cost traces.jsonl     # run without installing
pip install tracecost
Python 3.11+. No network access at runtime, no API keys, no telemetry.
- Three input formats, one model. OTLP JSON/JSONL with OpenTelemetry GenAI (
gen_ai.*) or OpenInference (llm.*) attributes, Phoenixget_spans_dataframeexports, and Langfuseobservations+tracesAPI responses load into the sameGenerationrecord. - Cache and reasoning tokens priced correctly. Cache read, cache write and reasoning tokens get their own rates; Langfuse's exclusive buckets are converted to OpenTelemetry's inclusive counts so nothing is double-counted (ADR-0004).
- A dated price table you can see and override. A bundled snapshot of
pydantic/genai-prices with tiers, dated price
changes (selected by each span's start time) and OpenAI service tiers;
--pricesadds your own models;tracecost prices gpt-5shows exactly what applied. - Rollups with no cutoff.
--by root|trace|session|user|model; root spans get the sum of everything beneath them, however deep. - Supplied costs honoured, then audited.
llm.cost.total,cost.amount/cost.sourceand LangfusecostDetailswin over the table and are labelled;--recomputeshows the gap. - Diff two runs.
tracecost diff before.jsonl after.jsonlmatches root spans by name and shows what moved in calls, tokens, cost and model mix;--fail-overturns it into a CI gate.
| tracecost | Langfuse / Phoenix | genai-prices | tokencost | OTel Collector gen_ai_normalizer |
|
|---|---|---|---|---|---|
| Reads exported trace files | OTLP, Phoenix, Langfuse | their own store | no (a price library) | no | no (live pipeline) |
Cross-dialect (gen_ai.*, llm.*, Langfuse) |
yes | each ingests its own + some conversion | n/a | n/a | OpenInference/OpenLLMetry → gen_ai.* |
| Cache read/write, reasoning, service tiers | yes | partly, varies by version | yes (data source) | no cache tiers | n/a |
| Re-price history after a price change | yes, offline | no, computed at ingest | yes (library) | yes | no |
| Supplied cost honoured and compared | yes | Langfuse yes, Phoenix re-derives | n/a | n/a | n/a |
| Rollups: root, trace, session, user, model | yes | yes, with the bugs cited above | no | no | no |
| Diff two runs | yes | no | no | no | no |
| Dashboards, traces UI, evals, alerts | no | yes | no | no | no |
| Live prices | no (dated snapshot) | yes | yes | stale since 2025-09 | n/a |
Langfuse and Phoenix are far more than this tool; use them to look at traces. tracecost is the offline second opinion on their numbers. genai-prices is where tracecost's prices come from.
export files ──► readers ──► Generation records ──► prices ──► rollup / diff ──► table · JSON
- Read. Each file is sniffed (
resourceSpans→ OTLP,context.span_id→ Phoenix,traceId→ Langfuse) and every span becomes aSpan; spans that carry a model or token usage also become aGeneration. Attribute names are tables, not code (readers/dialects.py). - Price. The model name is matched against the snapshot's match clauses (provider hint
first), the rates in force at the span's start time are resolved (dated prices, tiers,
service-tier variants), and
uncached_input × input + cache_read × cache_read + cache_write × cache_write + output × output + reasoning × (reasoning or output)is computed per generation. A supplied cost wins unless--recompute; the table figure is kept beside it. - Roll up. Every span's root is found by walking parent ids within the file; generations are summed per root, trace, session, user and model, and tool spans are counted per root.
- Report. A fixed-width table with aggregated warnings, or JSON with one row per generation for DuckDB and pandas.
Details: docs/concepts.md · docs/api.md · docs/quickstart.md · docs/faq.md.
- Prices are a snapshot. The header prints its date. Regenerate with
scripts/update_prices.pyor override with--prices; a provider's surprise price change is not known until then. - JSON-encoded OTLP only. Protobuf-binary and gzip exports are on the roadmap.
- Files, not servers. v0.1 reads what you export; it doesn't call the Langfuse or Phoenix API.
- Token semantics follow the OTel registry. If an exporter writes
gen_ai.usage.input_tokensexcluding cache tokens (Anthropic's rawinput_tokens), cache will be under-priced; compare the per-generation JSON with your raw usage once. See docs/faq.md. - Non-token costs on tool spans (OCR, GPU time on a retriever) are read only when attached to an LLM span; generic span costs are planned.
- Estimates, not invoices. Provider rounding, minimum charges, batch discounts and free tiers are not modelled.
- Read directly from the Langfuse public API and a Phoenix server (paginated), so the audit needs no manual export.
- Protobuf-binary and gzip OTLP input.
reconcile: compare totals with a provider's usage/billing CSV for the same period.- Cost attributes on tool and retriever spans in the same rollups.
- A GitHub Action wrapping
--fail-overfor recorded eval runs.
Bug reports with a small export that gives a wrong number are the most useful thing you can
send. See CONTRIBUTING.md for setup (uv sync, uv run pytest), how to add
an input format, and how to refresh the price snapshot.
MIT. The bundled price data is from pydantic/genai-prices, also MIT.