






Cloud | Documentation | Roadmap | Discord
📕 Table of Contents
RAGFlow is a leading open-source Retrieval-Augmented Generation (RAG) engine that fuses cutting-edge RAG with Agent capabilities to create a superior context layer for LLMs. It offers a streamlined RAG workflow adaptable to enterprises of any scale. Powered by a converged context engine and pre-built agent templates, RAGFlow enables developers to transform complex data into high-fidelity, production-ready AI systems with exceptional efficiency and precision.
Try our cloud service at https://cloud.ragflow.io.
For local deployment, see Local Deployment.


- 2026-09-29 RAGFlow 1.0.0-rc1 released.
- 2026-09-10 Added website content ingestion through sitemaps.
- 2026-08-19 Introduced Knowledge Compilation to generate Wikis, Graphs, Trees, PageIndex, Mind Maps, Timelines, and Skills at the document and dataset levels.
- 2026-08-19 Introduced Agentic RAG with Low, Medium, High, and Ultra thinking modes.
- 2026-07-02 Added Google BigQuery data source ingestion and incremental synchronization.
See the full release notes for more updates.
⭐️ Star our repository to stay up-to-date with exciting new features and improvements! Get instant notifications for new releases! 🌟

- Deep document understanding-based knowledge extraction from unstructured data with complicated formats.
- Finds "needle in a data haystack" of literally unlimited tokens.
- Intelligent and explainable.
- Plenty of template options to choose from.
- Compile content at the document and dataset levels into structured knowledge artifacts.
- Use compilation templates to generate Wikis, Graphs, Trees, PageIndex, Mind Maps, Timelines, and Skills for different knowledge organization and reuse needs.
- Configure compilation models and processing rules, and view, update, and regenerate knowledge artifacts.
- Perform multi-step retrieval for complex questions: the model analyzes the question and, when needed, breaks it down, retrieves knowledge, and verifies evidence.
- Gather more complete context through multiple rounds of retrieval and reasoning to help generate well-grounded answers.
- Choose Low, Medium, High, or Ultra thinking modes to control retrieval and reasoning depth according to question complexity.
- Visualization of text chunking to allow human intervention.
- Quick view of the key references and traceable citations to support grounded answers.
- Supports Word documents, PowerPoint presentations, Excel spreadsheets, TXT files, images, PDFs, scanned copies, structured data, web pages, and more.
- Streamlined RAG orchestration catered to both personal and large businesses.
- Configurable LLMs as well as embedding models.
- Multiple recall paired with fused re-ranking.
- Intuitive APIs for seamless integration with business.
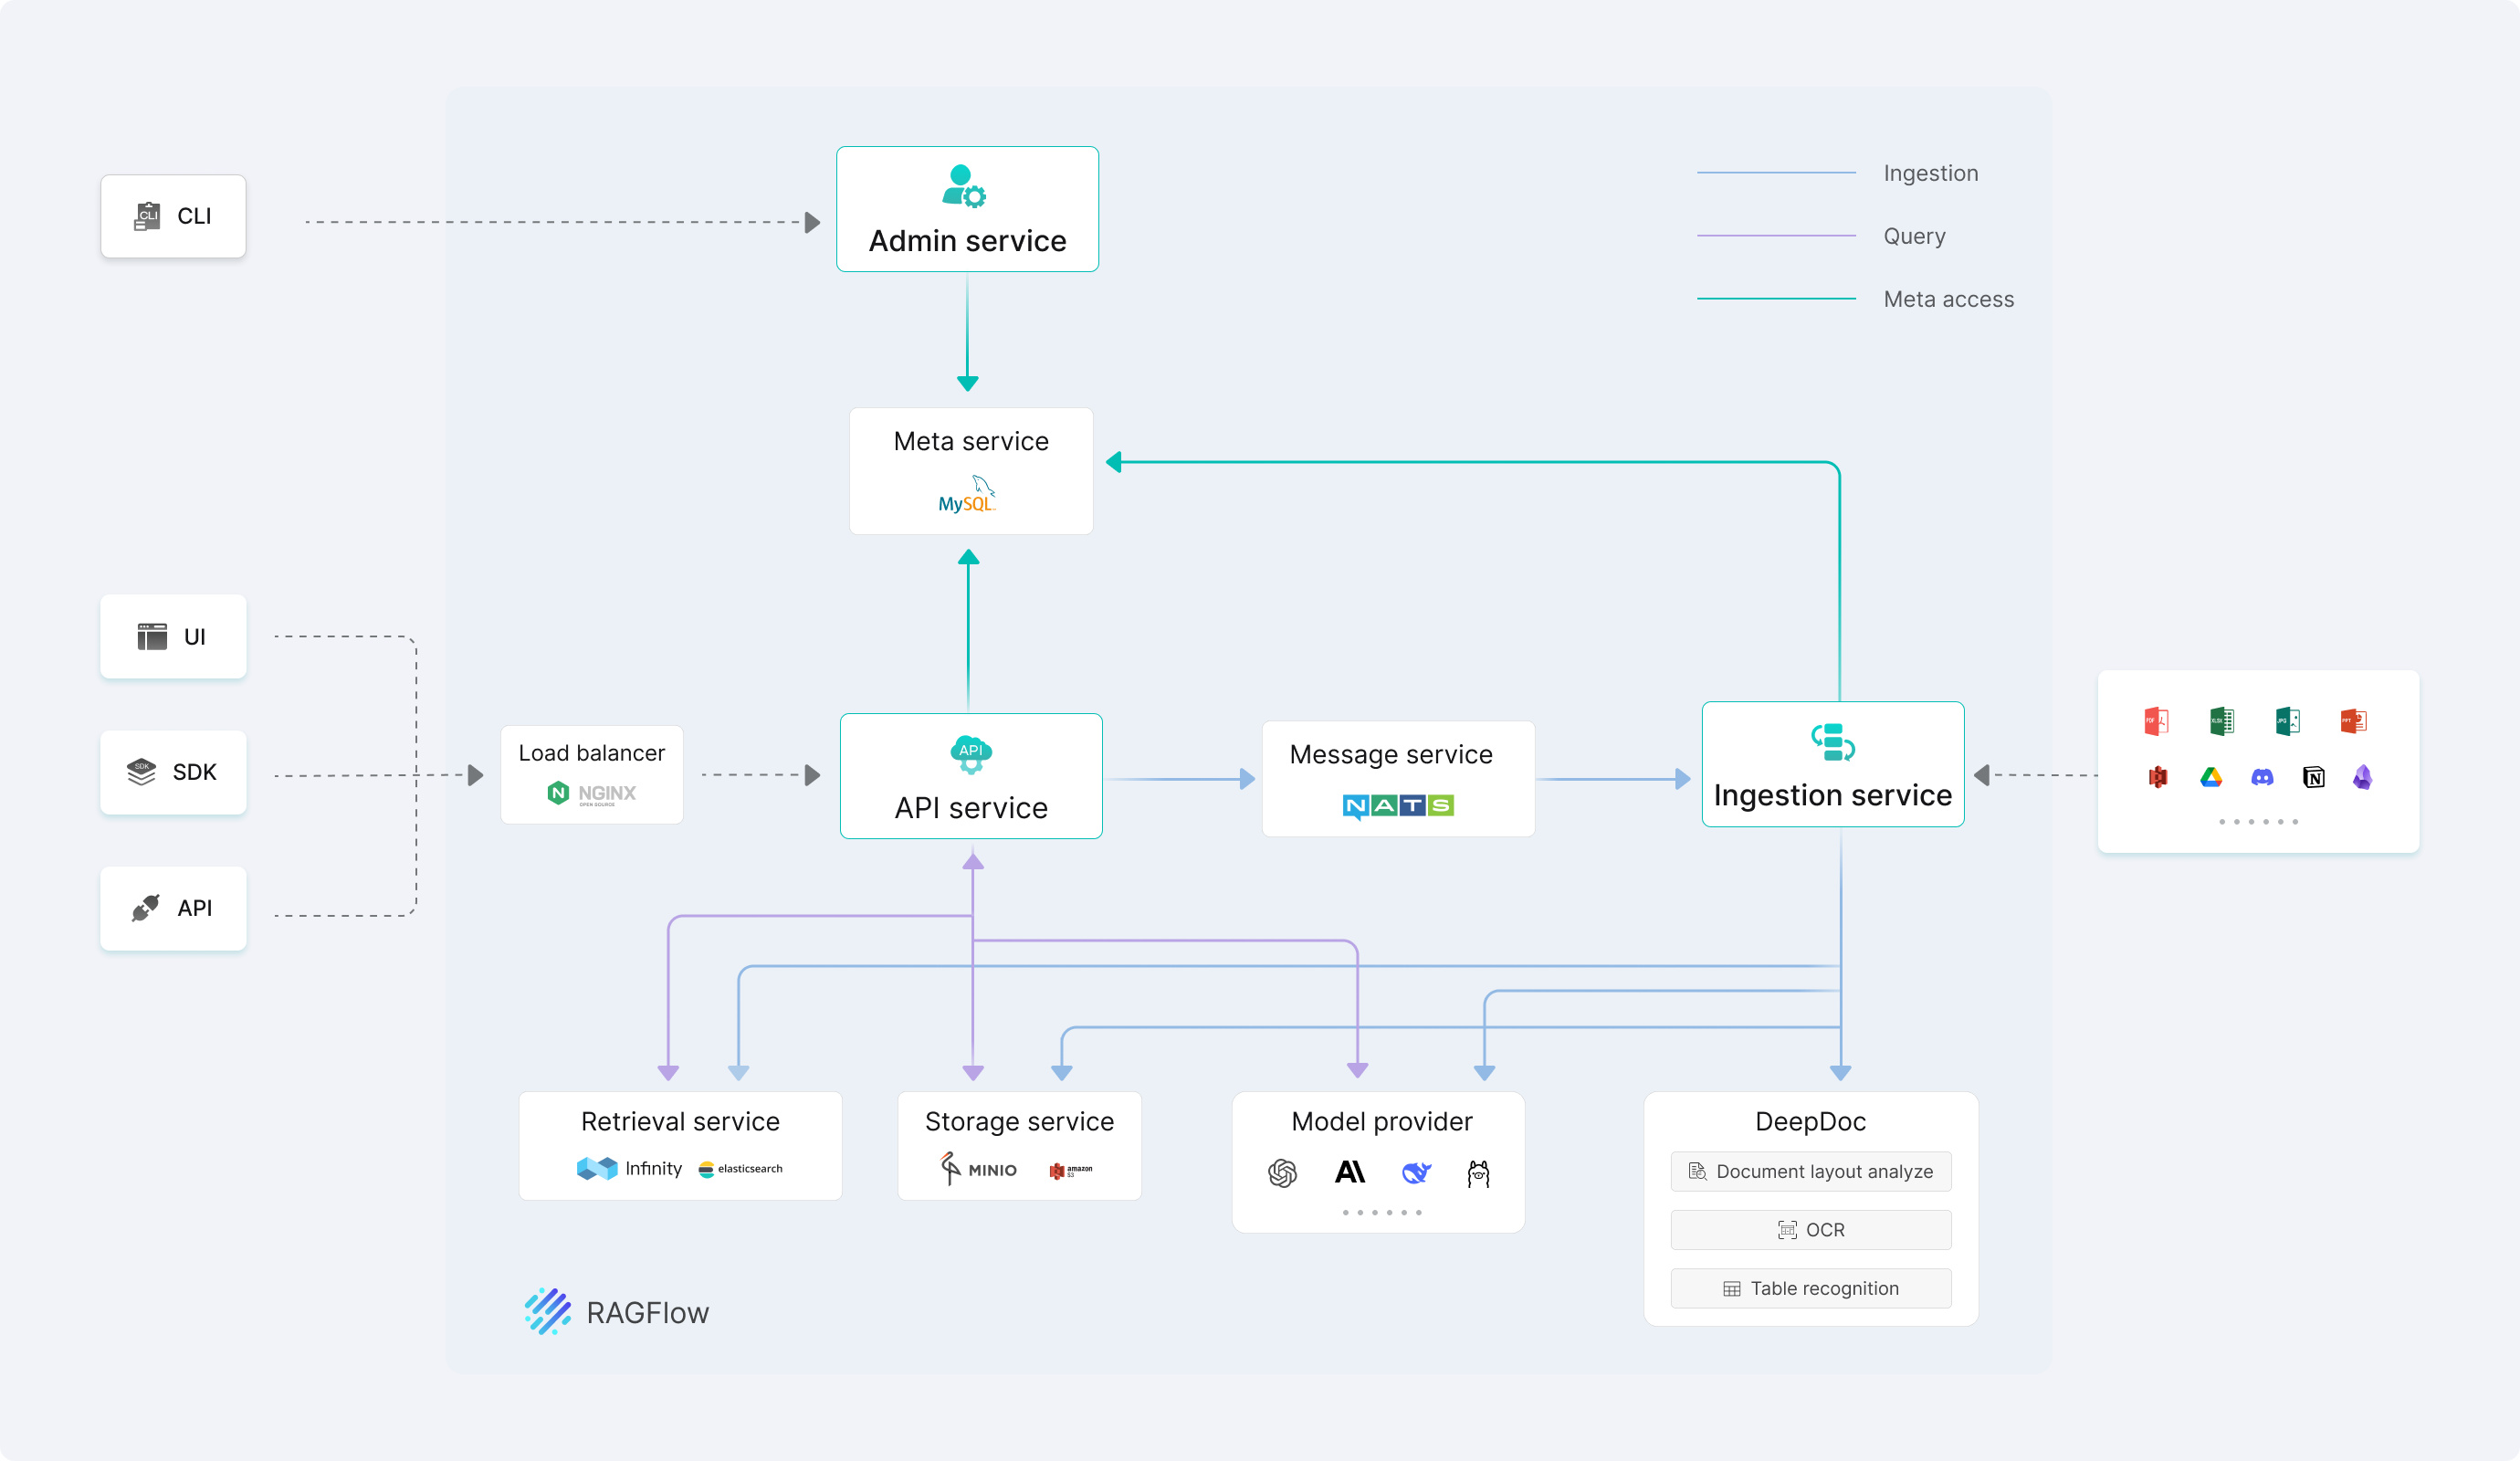
Local deployment supports both Docker deployment and launching from source. Docker is suitable for quick evaluation, integration testing, and production deployment, while launching from source is intended for RAGFlow development and debugging. Docker deployment does not require a Go compiler. Launching from source requires the Go version specified in go.mod; frontend development additionally requires Node.js and npm.
- Recommended starting configuration: 4 CPU cores, 16 GB RAM, and 50 GB of available disk space. Actual requirements depend on the document engine, data volume, parsing tasks, and concurrency. Local models and other optional components may require additional resources.
- Docker ≥ 24.0.0, Docker Compose ≥ v2.26.1.
Tip
If you have not installed Docker on your local machine (Windows, macOS, or Linux), see Install Docker Engine.
-
If using Elasticsearch, set
vm.max_map_counton the Docker host to at least 262144. This step is usually unnecessary with Infinity:To check the value of
vm.max_map_count:sysctl vm.max_map_count
If you use Elasticsearch and the value is below 262144, reset it:
# In this case, we set it to 262144:
sudo sysctl -w vm.max_map_count=262144
This change will be reset after a system reboot. To ensure your change remains permanent, add or update the
vm.max_map_countvalue in /etc/sysctl.conf accordingly:vm.max_map_count=262144
-
Clone the repository:
git clone https://github.com/infiniflow/ragflow.git
-
Check out the release tag and start the server with Docker Compose:
Enter the Docker deployment directory.
cd ragflow/dockerCheck out the
v1.0.0-rc2release tag.git checkout v1.0.0-rc2
Start the RAGFlow services and their dependencies.
docker compose -f docker-compose.yml up -d
With the default MySQL configuration, the image entrypoint runs database migrations before starting Admin, Syncer, Ingestor, API, and other services.
In the RAGFlow open-source 1.0 release, DeepDoc uses CPU inference for layout analysis, OCR, and table recognition.
-
Check the server status after startup:
Use
docker psto check the dependency services. After the dependencies showhealthyand the RAGFlow container remains running, use the HTTP endpoint to determine whether RAGFlow is ready. The RAGFlow container itself does not define a Compose healthcheck.curl -f http://localhost/api/v1/system/healthz
After receiving an HTTP 200 response, open the Web UI. If you changed
SVR_WEB_HTTP_PORT, replace the port in the health-check URL accordingly.If startup fails, inspect the container logs:
docker logs --tail 50 ragflow-cpu
-
In your web browser, enter the IP address of your server and log in to RAGFlow.
With the default settings, you only need to enter
http://IP_OF_YOUR_MACHINE(sans port number), because the default HTTP serving port80can be omitted when using the default configuration. -
After signing in, add an LLM, embedding, and reranker on the model provider page, including the model name, service address, and API key.
For details, see llm_api_key_setup.
The show is on!
See the Quickstart guide for details.
Docker deployment uses docker/.env and docker/docker-compose.yml. Configure the image, ports, passwords, document engine, and model image source as described in the Docker configuration guide. For platform support (note that macOS is not currently supported), see the Go Docker image build and platform support guide. To build the Docker image from source, see the Go Docker image build and platform support guide.
For document-engine changes, configuration updates, restarting services, and retaining or removing existing data, follow the Docker configuration guide.
-
Clone the repository and install the Go version specified in
go.mod(currently Go 1.27), Clang 20, LLD 20, CMake ≥ 4.0, and PCRE2 development files. Go services depend on CGO and native static libraries; build.sh sets the required build parameters.git clone https://github.com/infiniflow/ragflow.git cd ragflow -
Run the dependency download script once to prepare everything the local Go server needs to build, run, parse documents and count tokens (
download_dev_deps.pyfetches the native static libraries and the runtime resources — cl100k vocabulary, DeepDoc.ortweights, embedding tokenizer assets):uv run tools/scripts/download_dev_deps.py
This is the local-dev one-stop: after one run the environment is ready, and already-present files are skipped so re-running never re-downloads. The image-facing counterpart
ragflow_deps/download_deps.pyfetches the same runtime resources PLUS the stagehand server binary (used by the Browser component) and skips the native.afiles — run it only when building the dependency image or in CI, not for local development.download_dev_deps.pypulls and unpacks pdfium, pdf_oxide, office_oxide, and onnxruntime under~/ragflow-native-libs, and writes the cl100k vocabulary, DeepDoc models, and embedding tokenizer assets underragflow_deps/. It is a Python script;uv runinstalls its declared dependencies (requestsandhuggingface-hub) automatically. Skip this step if you have prepared the same resources by other means. When started from the repository root, Go services automatically findinternal/rag/res/deepdoc; to start from another directory, setDEEPDOC_MODEL_DIRto its absolute path. -
Build the services:
./build.sh --all
-
Start the local dependency services and make sure the hosts and ports in conf/service_conf.yaml point to addresses accessible from the host. If using Elasticsearch, first set
vm.max_map_counton the Docker host to at least262144.sudo sysctl -w vm.max_map_count=262144 docker compose --env-file docker/.env -f docker/docker-compose-base.yml up -d --wait es01 mysql minio nats kvrocks
-
Migrate the database:
./bin/ragflow_server --migrate
-
Start the four services in four separate terminals:
Terminal 1: start Admin on port
9381../bin/ragflow_server --admin
./bin/ragflow_server --ingestor
Terminal 3: start Syncer.
./bin/ragflow_server --syncer
Terminal 4: start API on port
9380../bin/ragflow_server --api
The startup modes work as follows:
--migrate: Runs database migrations and exits when complete.--admin: Starts the Admin service for management and initialization operations.--ingestor: Starts the Ingestor service for data ingestion and parsing tasks.--syncer: Starts the Syncer service for external data source synchronization tasks.--api: Starts the API service for the Web UI and SDKs.
-
Only when developing the frontend, install Node.js and npm, then start the React frontend:
cd web
npm install
After the services start, confirm that the API is ready:
curl -f http://127.0.0.1:9380/api/v1/system/healthz
An HTTP 200 response indicates that the API is responding. See Launch Service from Source for complete frontend and DeepDoc verification steps.
See Launch Service from Source for details.
See the RAGFlow Roadmap 2026.
RAGFlow flourishes via open-source collaboration. In this spirit, we embrace diverse contributions from the community. If you would like to be a part, review our Contribution Guidelines first.